Data Mining, Classification
No description yet. This curated deck is ready for daily study.
Card preview (24)
Approaches to classification
Decision trees bayesian classification classification rules neural networks k-nearest nieghbours SVM
Classification Requirements
• Accuracy • Interpretability • Scalability • Noise and outlier management
Definition of classification
Given a collection of labels and one of data objects labelled, find a descripitve model that will enable to distinguish an object of one class from another.
Criteria to evaluate classification techniques
• Accuracy • Efficiency • Scalability • Robustness • Interpretability
Decision Trees, Hunt’s Algo
Dt -> set of training records that reach a node t. Steps: • if Dt contains records that belong to more than one class -> select the best attribute A on which to split Dt andbel nodet as A, split Dt in smaller subsets and recursively apply the procedure to each subset. • If Dt contains records that belong to the same class yt then t is a leaf node labeled as yt • if Dt is empty then t is a leaf node labelled as the default (most common) class.
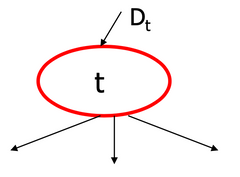
Decision tree induction
Adopts a greedy strategy -> not global optimum Issues: • structure of test conditions (binary splits vs multiway split): • depends on attribute type: nominal, ordinal, continuos. • selection of the best attribute for the split • stopping condition for the algorithm
Selection of best attribute in decision tree
Attributes with homogeneous class distribution are preferred, degree of impurity must be low. Node impurity needs a measure: • gini index • entropy • misclassification error Different algortithms rely on different measures of impurity.
GINI index
• Used to compute node impurity in decision trees • Maximum (1-1/nc) when records are equally distributed among all classes. • Minimum (0) when all records belong to one class.
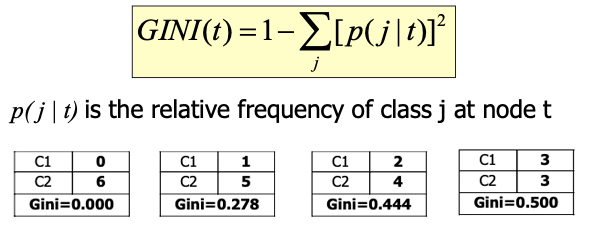
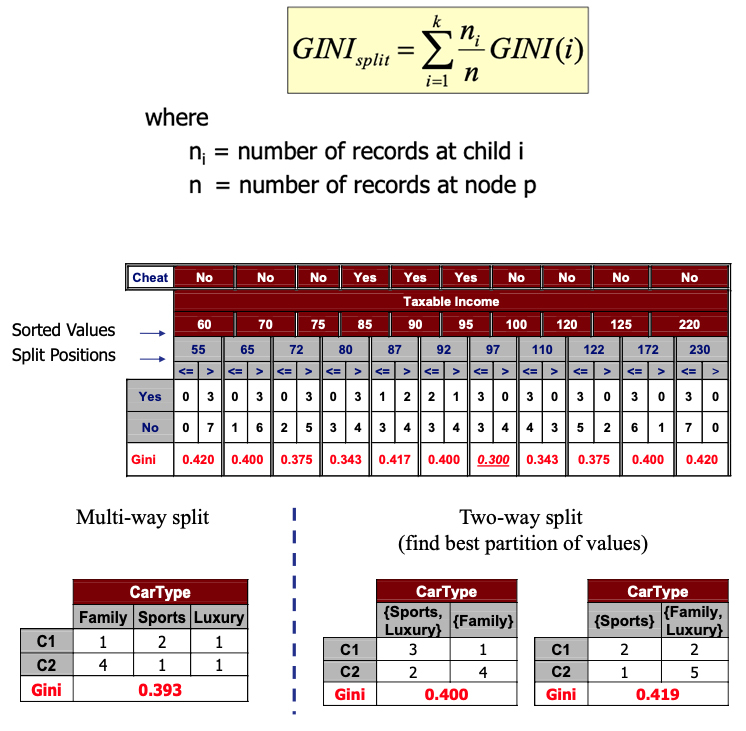
Computing quality of a split using GINI
This technique is used in CART, SLIQ, SPRINT When a node p is split into k partitions (children), the quality of the split is. Categorical attribute: • For each distinct value gather counts for each class in the dataset • use the count matrix to make decisions Continuos Attribute: • Binary decision on one splitting value • possible splittings = number of distinct values • Each splitting value has a count matrix • Sort attribute on value • Linearly scan these values, each time updating the count and computing gini index • Choose the split position that has the least gini index
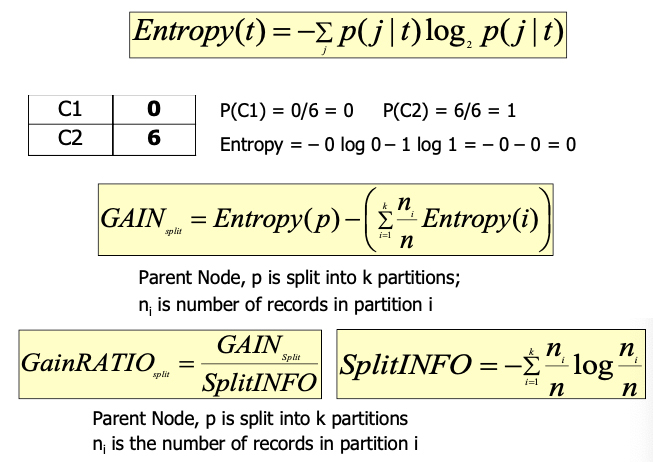
Entropy impurity measure (INFO)
INFO • max (log nc) when records are equally distributed • min (0) • Entropy computations are very similar to GINI index’s ones. Information gain: • measures reduction in entropy achieved because of the split. • Disadvantage: tends to yield higher number of partitions, each small but pure. Gain Ratio: • Adjust information gain by the entropy of the partitioning. Higher entropy partitioning is penalized. • Designed to overcome shortcomings of information gain.
Classification error impurity measure
Meausures classification error made by current node. Same maximum and mimum of GINI index.
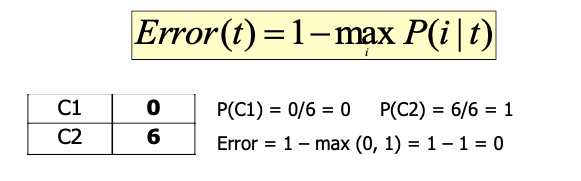
Stopping criteria for tree induction
Stop expanding node when: • All records belong to the same class • All the records have similar attribute values • Early termination: • pre-pruning • post-pruning
Overfitting vs Underfitting, Noise overfitting
Underfitting: model is too simple, training and test set errors are high.
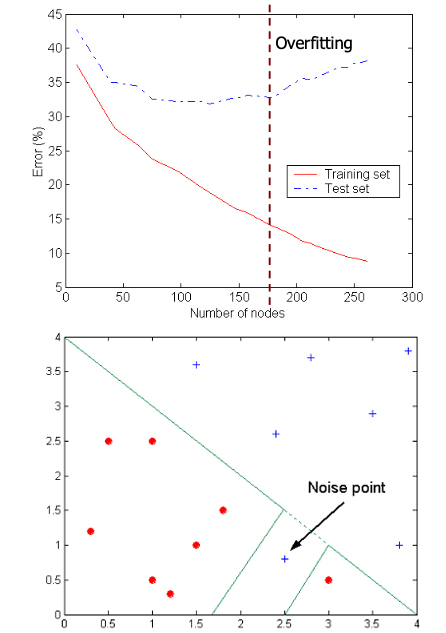
Addressing overfitting
Pre-pruning (early stopping): • Stop the algo before it becomes a fully-grown tree • Typical stopping conditions for a node • if all instances belong to same class • all the attribute values are the same • More restrictive conditions: • Stop if cardinality of instances is less than some user-specidfied threshold • Stop if class distribution are independent of the available features • Stop if expanding the current node does not improve impurity measures Post-pruning: • Grow decision tree to its entirety • Trim the nodes of the decision tree in a bottom up fashion • If generalization error improves after trimming, replace sub-tree by a leaf node. • Class label of leaf node is determined from majority class of instances in the sub-tree
Issues of decisions tree
• Data fragmentation • Number of instances gets smaller as you travers down the tree, and that could be too small to make any statistically significant decision. • Handling missing attribute values • affect how impurity measures are computed • affect how to distribute instance with missing value to child nodes • Affect how a test instance with missing value is classified. • Search strategy • Finding optimal decision tree is NP-hard • Algorithm presents so far uses a greedy, top-down, recursive partitioning strategy. • Expressiveness • Decision tree provide expressive representation for learning discrete-valued function (example: parity function) • Not expressive enough for modeling continuos variables, in particular when test condition involves only a single attribute at a time. • Tree Replication
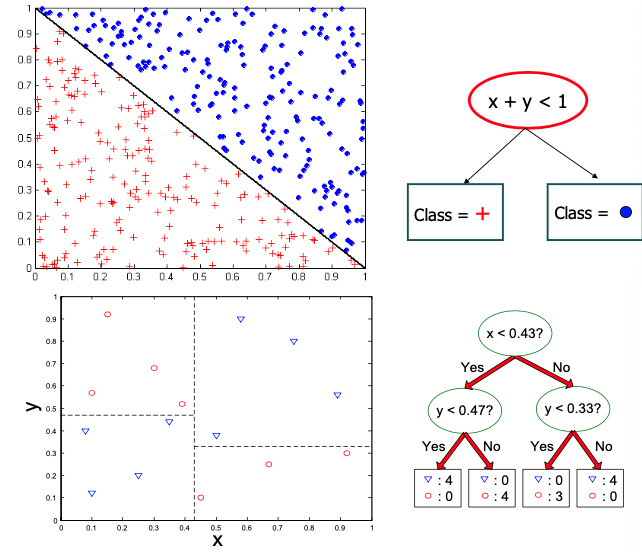
Tree decision boundary and Oblique decision trees
Border line between two neighboring regions of different classes is known as decision boundary Decision boundary is parallel ot axes because test condition involves a single attribute at a time. In oblique decision trees, test condition may involve multiple attributes, more expressive representation. Finding optimal test condition is computationally expensive.
Pros and cons of decision tree based classification
Pros: • Inexpensive to construct • extremely fast at classifying unknown records • easy to interpret for small-sized trees • accuracy is comparable to other techniques for many simple data sets Cons: • Accuracy may be affected by missing data.
Rule Based classifier
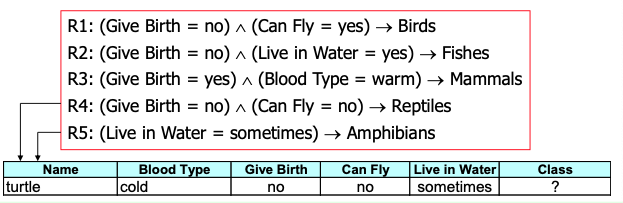
Classify records by using a collection of if … then … Rule: (Condition) → y • Condition is a conjuction of attributes • y is the class label A rule r covers an instance x if the attributes of the instance satisfy the condition of the rule. Example: R1: (Give birth = no) ⋂ (Can fly = yes) → Birds Characteristics of rules: • Mutually Exclusive: every record is covered by at most one rule • Exhaustive rules: Classifier rules account for every possible combination of attributes, so that each records is covered by at least one rule. Advantages of rule-based classifier: • Performance, and expressiveness comparable to decision trees. • Easy to generate and interpret • Fast classification
Rules semplification: problems and solutions
From: (Refund=No) ⋂ (Status=Married) → No To: Simplified Rule: (Status=Married) → No Problems: • Rules are no longer mutually exclusive (more than one rule could be triggered) • Make oredered rule set or • Unordered rule set - using voting schemes • Rules are no longer exhaustive • A record may not trigger any rules • Solution: use a default class
Ordered rule set
Rules are rank ordered according to their priority. When a test record is presentd to the classifier it is assigned to the class lable of the highest ranked rule it has triggered. If no rules were triggered, it is assigned to the default class.
Methods to build classification rules
Direct method: • Extract rules from data (RIPPER, CN2, Holte’s 1R) Indirect Method: • Extract rules from other classification models (decision trees, neural networks)
Associative classification
The classification models defined by means of associaltion rule: (Condition) → y rule body is an itemset. Model generation: • Rule selection & sorting: based on support, confidence and correlation thresholds • Rule pruning: the training set is covered by selecting the topmost rules according to previous sort (database coverage)
Pros and cons of associative classification
Strong points: • Interpretable model • higher accuracy than decisions trees • efficient classification • unaffected by missing data • good scalability Weak points: • Rule generation may be slow • Depends on support threshold • Reduced scalability in the number of attributes • Rule generation may become unfeasible